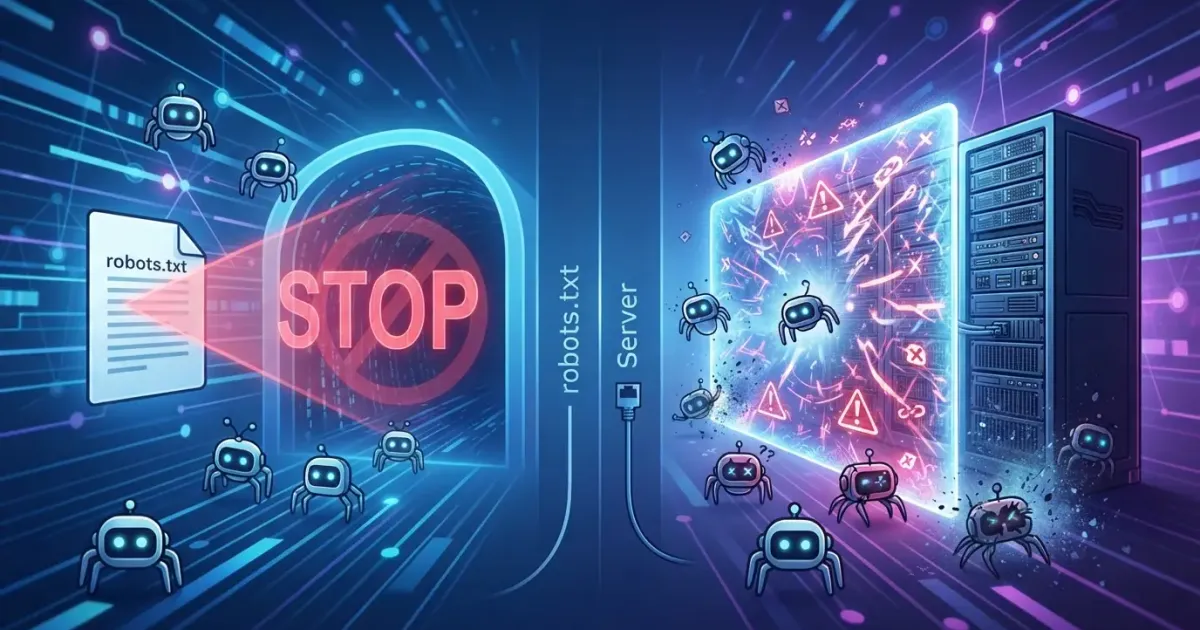
Blocking AI crawlers can be done several ways, but each approach carries a different level of effectiveness. Robots.txt is the simplest way to tell a crawler not to access a specific part of a site, while a CDN, Web Application Firewall (WAF), and server-level rules can actually reject a request before any content is served.
In Search Engine Journal's discussion on blocking AI crawlers via robots.txt or the server, Helen Pollitt explains that the technical decision depends on business goals, website architecture, cost, and who manages the infrastructure. No single method is always the right fit for every site.
The most important distinction is simple: robots.txt relies on crawler compliance, while blocking at the WAF, CDN, or server level is enforcement. If a crawler ignores the robots.txt instructions, nothing in that file physically stops the request.
Table of Contents
- What's the Difference Between Robots.txt and Server-Level Blocking for AI Crawlers?
- How Do You Block AI Crawlers Through Robots.txt?
- Is Robots.txt Enough to Block AI Crawlers?
- How Does Server-Level Blocking Work?
- Why Is a CDN More Efficient Than Blocking at the Origin Server?
- Why Is a WAF Considered the Strongest Layer for Blocking AI Scrapers?
- Which Is Better: Robots.txt, CDN, WAF, or Server?
- What's the Risk of Misconfiguring Robots.txt?
- What's the Risk of Misconfiguring a WAF or CDN?
- Can Blocking AI Crawlers Affect Visibility in AI Search?
- How Do You Decide Whether an AI Crawler Deserves to Be Blocked?
- Why Do Server Logs Matter After Blocking an AI Crawler?
- When Is Robots.txt Enough on Its Own?
- When Should You Move Up to a WAF or CDN?
- FAQ About Blocking AI Crawlers
- Can robots.txt really stop an AI crawler?
- Is a WAF more effective than robots.txt?
- Can a CDN save bandwidth when blocking bots?
- Is a user-agent enough to detect an AI crawler?
- Should every AI crawler be blocked?
- What's the best method if I genuinely don't want AI scrapers accessing my site at all?
- Conclusion
What's the Difference Between Robots.txt and Server-Level Blocking for AI Crawlers?
Robots.txt is a protocol that gives a crawler instructions about which areas of a site it may or may not crawl. Server-level blocking operates at the request layer and can reject a connection or response based on user-agent, IP, headers, traffic patterns, or other rules an administrator configures.
The robots.txt concept was originally designed as a communication mechanism between a site owner and web crawlers. The file doesn't function like a firewall. That means a bot that chooses not to comply can still technically request the page.
A server, CDN, and WAF are different because they sit directly in the request path. If a rule flags a request as a bot that should be blocked, that request can be stopped without the crawler ever needing to "agree" to your policy.
Method | Nature | Main Strength | Limitation |
|---|---|---|---|
robots.txt | Declarative | Easy, cheap, granular per user-agent/path | Depends on crawler compliance |
Server rule | Enforcement | Can reject requests directly | Needs technical access and maintenance |
CDN | Edge enforcement | Stops the request before it reaches the origin server | Depends on provider features |
WAF | Enforcement + behavioral filtering | Stronger at detecting spoofing and bot patterns | More complex and can add cost |
How Do You Block AI Crawlers Through Robots.txt?
The method is the same as blocking any other crawler: identify the bot's user-agent, then add a Disallow rule to the robots.txt file.
For example, to keep GPTBot from accessing the entire site:
User-agent: GPTBot
Disallow: /
If you only want to block a specific directory:
User-agent: GPTBot
Disallow: /products/
According to the SEJ article, several major AI companies publish specific user-agents, including GPTBot and OAI-SearchBot from OpenAI, ClaudeBot and related crawlers from Anthropic, Google-Extended from Google, and PerplexityBot from Perplexity.
The upside is that rules like these are easy to implement and can be very granular. You can block one crawler while allowing another, or restrict access to just one directory.
But the core weakness never changes: robots.txt is a request, not a technical barrier. A non-compliant bot can still send requests to a blocked URL.
Is Robots.txt Enough to Block AI Crawlers?
Robots.txt is enough if your goal is closer to "stating a preference" to well-behaved crawlers, rather than absolutely guaranteeing content can't be accessed.
As a simple analogy, robots.txt is like a "no entry" sign in front of an unlocked gate. A crawler that follows the rules will stop. One that doesn't can still walk right through.
For a site that only wants to keep out one or two well-known crawlers, this approach can be practical enough. Search Engine Journal recommends keeping an eye on server logs to confirm that bots blocked via robots.txt have actually stopped accessing the site.
The situation is different if the reason for blocking involves protecting intellectual property, server load, mass scraping, or a legal policy that requires stronger enforcement. In those cases, relying on robots.txt alone is too weak.
How Does Server-Level Blocking Work?
Server-level blocking reads incoming requests and applies rules based on attributes like user-agent, IP address, headers, or request patterns. If a request matches a given rule, the server can reject it.
In simple terms, the flow looks like this:
Incoming Request
      ↓
Server Rule
      ↓
Does the request match a bot rule?
      ↓
Yes → Deny / 403 / Drop
No → Continue normal processing
This approach is stronger than robots.txt because the crawler isn't being asked to comply. The server itself decides whether to accept or reject the request.
The downside is that configuration like this usually isn't in the SEO team's hands. Changes typically require a developer, DevOps, or infrastructure engineer, especially in a production environment with strict change management.
Why Is a CDN More Efficient Than Blocking at the Origin Server?
A CDN can stop a request before it ever reaches the origin server. That reduces bandwidth, CPU, memory, and request-processing load on your core infrastructure.
Picture a bot sending millions of requests to a product page. If blocking only happens at the origin, those requests still reach your server before getting rejected. If they're blocked at the CDN edge instead, most of them stop much earlier.
For large sites, or websites facing mass scraping, this can meaningfully affect infrastructure cost and application stability.
Search Engine Journal cites Cloudflare as an example of a CDN that offers preset blocking for specific bot categories, including search bots, agents, and crawlers used for training. But the specific implementation depends heavily on the provider and the service tier in use.
Why Is a WAF Considered the Strongest Layer for Blocking AI Scrapers?
A WAF doesn't just read a bot's claimed identity through its user-agent. It can also analyze request behavior, traffic patterns, rate, header combinations, and other security signals.
This matters because a user-agent is trivially easy to fake. A scraper can alter its headers to look like a normal browser, or even like a different, allowed crawler.
According to the SEJ article, a WAF is the strongest option in many tech stacks for detecting more sophisticated AI crawlers that try to dodge simple blocking.
But "strongest" doesn't mean perfect. A sufficiently sophisticated bot can still try to slip past validation checks using distributed IPs, headless browsers, residential proxies, or other techniques that make its traffic look human.
In other words, the realistic goal is to significantly raise the cost and difficulty of scraping — not to assume there's a blocking system that's impossible to get past.
Which Is Better: Robots.txt, CDN, WAF, or Server?
If your blocking needs are genuinely strong, the more sensible approach is to block as early as possible in the server stack. The order SEJ's article recommends is WAF where available, then CDN, then server-level rules.
- Use a WAF when you need strong enforcement and more sophisticated bot-behavior detection.
- Use CDN blocking when you want to stop bots before they reach the origin and save on bandwidth.
- Use a server rule when you don't have control over a WAF or CDN but still need enforcement.
- Use robots.txt when you just need to ask well-behaved crawlers not to access certain content.
For sensitive needs, combining several layers is safer than relying on a single control.
What's the Risk of Misconfiguring Robots.txt?
The most dangerous mistake is a rule that's too broad and accidentally blocks an important crawler.
For example:
User-agent: *
Disallow: /
A rule like this asks every crawler that respects robots.txt to stop crawling the entire site. If this gets applied by accident on a production website, the impact on search engine discovery and crawling can be serious.
Another problem is maintenance. The list of AI crawlers keeps changing, and new user-agents can appear at any time. Robots.txt doesn't automatically update its rules when an AI company introduces a new bot.
Because of that, this file should be treated as production configuration with an owner, a review process, and version history — not something anyone can edit without review.
What's the Risk of Misconfiguring a WAF or CDN?
The risk is bigger here, because enforcement happens before the request ever reaches the application. A bad rule can block legitimate users, important search crawlers, a monitoring service, a payment webhook, an API partner, or an internal integration.
Some common risks:
- False positives on normal user traffic.
- Accidentally blocking Googlebot or another search engine crawler.
- Rate limiting that's too aggressive.
- An IP rule that's too broad.
- Cache behavior changing after a bot-management configuration.
- Internal API traffic getting caught up in it too.
Because of that, deploying a new rule should start in a monitoring or logging mode if the provider supports it. Review which requests would get blocked before fully switching on a deny rule.
Can Blocking AI Crawlers Affect Visibility in AI Search?
It can. The decision to block a crawler isn't just an infrastructure decision — it's also a content-distribution decision.
If an AI system needs a specific crawler to discover or fetch content, blocking that crawler can reduce the odds of your content showing up in that particular AI experience. But this relationship isn't always straightforward, since an AI company can operate several crawlers with different purposes.
Because of that, don't block every user-agent associated with a company based on the brand name alone. First identify each crawler's actual function: is it used for training, search indexing, user-requested fetching, an agent, or some other purpose?
This is also why blocking policy should be owned across teams: SEO, legal, security, infrastructure, and business stakeholders all need to agree on the same goal.
How Do You Decide Whether an AI Crawler Deserves to Be Blocked?
Start from business goals, not from a general sentiment about AI.
- Identify the crawler. Confirm that the user-agent and the request's source genuinely correspond to the service in question.
- Measure request volume. Check server logs, bandwidth, response codes, and the endpoints accessed most often.
- Assess the benefit. Could this crawler generate referrals, citations, discovery, or visibility?
- Assess the cost. Calculate the bandwidth, CPU, scraping pressure, and maintenance it creates.
- Determine content sensitivity. A public article is different from a proprietary dataset or premium content.
- Choose your blocking layer. Use robots.txt for a declaration; use a WAF/CDN/server when enforcement is required.
- Monitor after implementation. Confirm the target bot's traffic has genuinely dropped without damaging legitimate traffic.
If your team has previously covered technical SEO and crawling, the internal article Cache Busting Sitemaps for SEO: Why Google Doesn't Recommend It can serve as an internal silo link once the previous article's URL is verified.
Why Do Server Logs Matter After Blocking an AI Crawler?
Server logs provide evidence of whether a rule is actually working. Without logs, a team only knows the configuration has been deployed — not whether the crawler is still trying to get in, switching user-agents, or using a different path.
Data worth monitoring includes:
- User-agent.
- IP or network origin.
- Request path.
- Response code.
- Requests per minute.
- Bandwidth used.
- Repeating request patterns.
From there, a team can see whether robots.txt is enough or whether additional enforcement is needed.
When Is Robots.txt Enough on Its Own?
Robots.txt makes sense when you're blocking a reputable crawler that explicitly states it follows the protocol, the bot traffic doesn't create a meaningful load, and there's no legal or security requirement demanding stronger enforcement.
For example, a public blog might not mind that ordinary users can still access its content, but wants to state that a particular training crawler shouldn't crawl its pages. In a situation like that, robots.txt gives simple control without adding infrastructure complexity.
Still, keep monitoring. If the targeted crawler keeps showing up in the logs, the team needs to evaluate whether the bot's identity is correct, whether the rule is right, or whether another layer is needed.
When Should You Move Up to a WAF or CDN?
Use a WAF or CDN once the cost and risk of bot access are high enough that simply "asking" the crawler to stop isn't sufficient.
Some indicators:
- AI scraper request volume is very high.
- The origin server is carrying extra load.
- The content has high commercial value.
- A crawler is ignoring robots.txt.
- User-agents keep changing or look spoofed.
- The team needs clearer blocking logs.
- There's a legal or licensing policy around content use.
In these conditions, a WAF or CDN isn't just an SEO tool anymore. It becomes part of content-access governance.
FAQ About Blocking AI Crawlers
Can robots.txt really stop an AI crawler?
Not technically. Robots.txt is a declaration that depends on crawler compliance. A bot that ignores it can still send requests to your server.
Is a WAF more effective than robots.txt?
Yes, for enforcement. A WAF can block requests based on rules and behavioral patterns without needing the bot's cooperation.
Can a CDN save bandwidth when blocking bots?
Yes. Since requests can be stopped at the edge before reaching the origin, a CDN can reduce bandwidth and server load.
Is a user-agent enough to detect an AI crawler?
Not always. A user-agent can be faked. For more aggressive crawlers, you need a combination of behavioral detection, IP intelligence, rate analysis, and WAF rules.
Should every AI crawler be blocked?
No. The decision should weigh business goals, visibility, infrastructure cost, content sensitivity, and each crawler's actual function.
What's the best method if I genuinely don't want AI scrapers accessing my site at all?
Based on the recommendation Search Engine Journal discusses, block as high up in the server stack as possible: WAF where available, then CDN, then server-level rules. Robots.txt can still be used as an additional declaration.
Conclusion
Blocking AI crawlers doesn't have a single method that's always correct. Robots.txt is easy to implement and effective against reputable, compliant crawlers, but it provides no technical enforcement.
If your blocking needs are more serious, a WAF, CDN, or server-level rule is far stronger, because a request can be rejected before any content is served. A WAF usually offers the most complete capability against spoofing and more complex crawler patterns, while a CDN helps reduce origin load.
What matters most is not blocking based on assumptions. Identify the crawler, weigh the benefit against the cost, understand what the user-agent actually does, then monitor the logs after the rule goes live. Blocking AI crawlers is an SEO, infrastructure, security, and business decision all at once.
If your business needs to design a bot-management strategy, CDN/WAF configuration, technical SEO, or more controlled crawling architecture, you can discuss your business's technology needs with our technical team.
Comments
Got a question or feedback? Leave a comment!